NVIDIA's open Nemotron 3.5 Bolt 74B squeezes into 24 GB for local AI agents
The 74B mixture-of-experts model with 9B active parameters lands on 15 October for RTX Spark, and NVIDIA's PAIR router for spreading AI jobs across home PCs leaves beta.
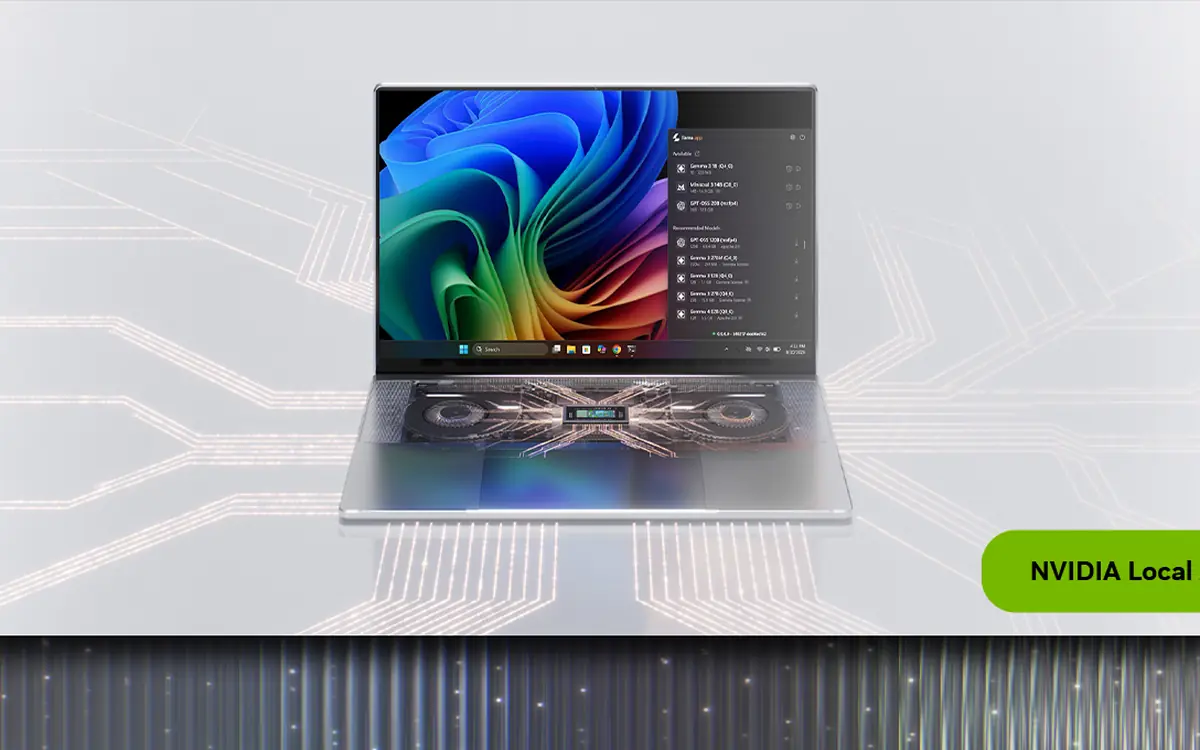
Two days before RTX Spark laptops go on sale (16 October), NVIDIA has set out the software it wants running on them. The headline item is a new open model, Nemotron 3.5 Bolt 74B, which NVIDIA says is built specifically for running AI agents locally rather than in the cloud.
A 74B model in 24 GB
Bolt 74B is a mixture-of-experts model with 74 billion parameters, of which about 9 billion are active for each token. NVIDIA packs it into 24 GB using 2-bit quantisation trained with quantisation-aware techniques, which are meant to keep quality from collapsing at such low precision. The company's claim is that it is faster than most popular dense models and smarter than most MoE models with a similar memory footprint. That comparison is NVIDIA's own, and we have not seen independent tests.
The model releases on Thursday, 15 October. NVIDIA says it will run at launch in llama.cpp, vLLM, Ollama, Unsloth and LM Studio, and be available directly in agent apps such as Hermes and OpenClaw. Like other Nemotron releases, it is fully open: weights, training data and training recipes are all published.
PAIR leaves beta
NVIDIA PAIR, a free, open-source "personal AI router", is now out of beta. It finds compatible machines on your local network, installs models and inference engines, and spreads AI workloads across them. Version 1.0 adds llama.cpp support, direct model downloads from Hugging Face, adjustable engine settings and RTX Spark support. PAIR runs on Windows, Linux and macOS.
Safer agents and hybrid routing
NVIDIA also highlighted sandboxing for local agents. OpenShell sits on top of Microsoft's Execution Containers (MXC) and adds credential protection and security monitoring. OpenClaw and GitHub Copilot already support MXC, and Hermes plans to add it by the end of October. For people who want both local and cloud models, NVIDIA's open-source Switchyard library sends each query to a local or cloud LLM, and Hermes plans to adopt it later this month.
What else is coming
- Broadcast 2.3 is out now, with Video Super Resolution, Frame Generation, offline file processing and an MCP server for agent control.
- Nemotron 3.5 Bolt E4B 4GB, a small model for in-game AI characters, arrives on 23 October alongside SkyrimNET.
- Llama.cpp now supports fast "decision models" and has a Windows tray app.
If you are wondering how much memory local models really need, see our laptop for local AI guide.
More from Computers & AI
View all →Read next
GTA VI launch trailer is live — five weeks to November 19
Rockstar dropped the Grand Theft Auto VI Launch Trailer on 15 October, with new PS5-captured footage and a debut score track, ahead of the 19 November release.
How to choose wireless earbuds in 2026
Fit, ANC, codecs, battery, multipoint and IP rating: a practical buying guide to true wireless earbuds without invented lab scores or brand rankings.
How to choose a home EV charger: power, phases, smart features and safety
Granny cable or wallbox, 7.4 or 11 kW, tethered or socket, smart tariffs and RCD protection: what to check before you buy and install a home EV charger.